The short answer
An AI model can only answer from the data it is given. If that data is old, duplicated or incomplete, the AI gives confident but wrong answers. Data engineers build the pipelines that collect data from apps, databases and files, clean it, and deliver it fresh every day. Models change every few months, but the pipelines that feed them stay, which is why data engineering matters more in the AI age, not less.
In this article (7 sections)
01A wrong price for three days
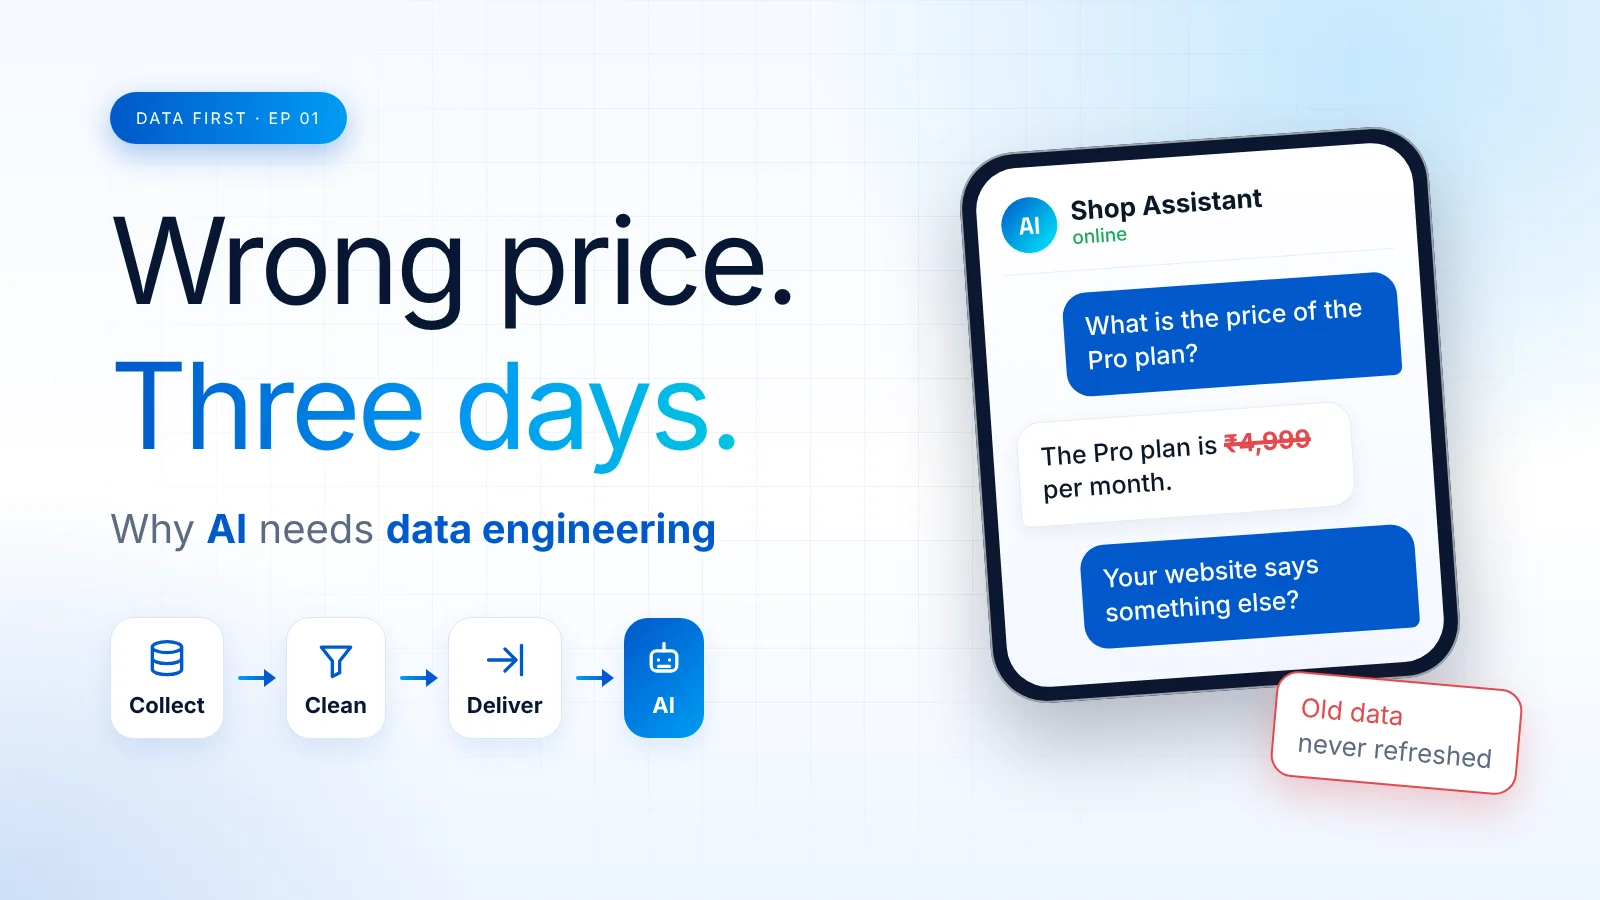
Here is a simple example. An online shop adds an AI chat assistant to answer customer questions. The prices on the website change, but the data the assistant reads is never refreshed. For three days, it tells every customer the old price, politely and with full confidence.
Nothing was wrong with the model. It did exactly what it was built to do: answer from the data it had. The problem was the data, and fixing that is not an AI job. It is a data engineering job.
The model was not wrong. The data was old.
02What AI needs before it can answer anything
Every chatbot, recommendation, forecast and dashboard depends on data that is:
- Collected from the places it actually lives: app databases, CRMs, logs, files and APIs
- Cleaned, so duplicates, missing values and wrong formats do not reach the model
- Up to date, refreshed on a schedule the business can trust
- Delivered in the right shape and the right place, where the AI or the analyst can read it
None of this happens on its own. Someone has to design it, build it, schedule it and watch it every day. That someone is a data engineer.
03What a data engineer does: collect, clean, deliver
| Step | What happens | Example on AWS |
|---|---|---|
| Collect | Pull data from apps, databases, files and APIs into one place | Land raw files in Amazon S3, trigger loads with AWS Lambda |
| Clean | Remove duplicates, fix types and formats, apply business rules | Transform with PySpark jobs on AWS Glue |
| Deliver | Publish trusted, up to date tables for AI, apps and reports | Query the curated tables with Amazon Athena |
| Watch | Check every run, alert when data is late or wrong | Job monitoring and alerts on each pipeline run |
Swipe sideways to see the full table
This is a pipeline. It runs every day, often every hour, without anyone pressing a button. When it works, nobody notices. When it breaks, the AI starts giving wrong answers.
Here is what one small piece of the Clean step looks like. If the price table gets a new row every time a price changes, this query keeps only the latest price for each product, so the AI never reads an old one:
-- Keep only the most recent price for each product
SELECT product_id, price, updated_at
FROM (
  SELECT product_id, price, updated_at,
         ROW_NUMBER() OVER (
           PARTITION BY product_id
           ORDER BY updated_at DESC
         ) AS rn
  FROM raw_prices
) latest
WHERE rn = 1;04How bad data breaks AI
- Stale data: the AI answers from yesterday's or last week's numbers, like the wrong price above
- Duplicates: the same customer or order counted twice, so totals and answers are inflated
- Missing data: a source failed to load, and the AI quietly answers from half the picture
- Mismatched meanings: two systems use the same word for different things, and the AI mixes them up
- No monitoring: nobody knows the data is wrong until a customer complains
05Models change, pipelines stay
New AI models arrive every few months, and teams switch between them often. The data foundation underneath does not get replaced that easily. The pipelines that collect, clean and deliver the company's data keep running through every model change, and they need people who can build and maintain them.
That is why data engineering becomes more important as companies adopt AI. Every new AI feature adds another consumer of data, and every consumer needs data that is correct, complete and on time.
06Skills you need to start in data engineering
- SQL: the language you will use every single day
- Python and PySpark: to write transformations that run on large data
- Cloud basics on AWS: S3 for storage, Glue for processing, Athena for querying
- Data modelling: how to shape tables so they are easy and correct to use
- Scheduling and monitoring: making pipelines run on time and alert when they fail
You do not need to be an AI researcher to work on AI projects. If you can build reliable pipelines, you are the person every AI team needs first.
07About Data First
Data First is a short series from D2X Technologies on the data skills behind AI. Each episode explains one concept simply, with a short video and an article like this one. Next up: slowly changing dimensions, SCD Type 1 vs Type 2, with Apache Iceberg MERGE.
Next in Data First
SCD Type 1 vs Type 2, with Apache Iceberg MERGE
Coming soon. Follow D2X Technologies on Instagram or YouTube to catch it first.